Roger Dunham

Travis Montgomery
Senior Solutions Engineer
Published October 31, 2025
Updated October 23, 2026

11 min


FOIA Redaction: Removing Exempt Content From Public Records
Roger Dunham
Travis Montgomery
Senior Solutions Engineer
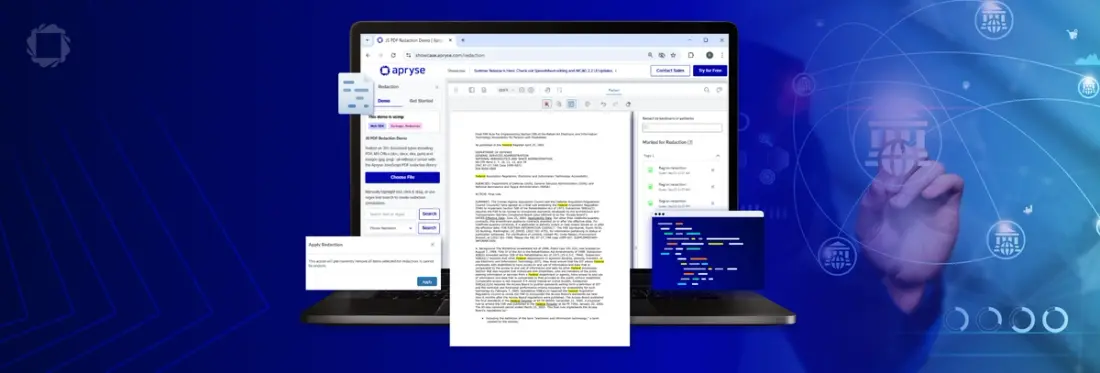
Responding to a FOIA request means releasing a record with the exempt parts permanently removed, not hidden. This article covers the records workflow first, exemptions, reviewer approval, audit trail and where records are processed, then the implementation, with working C# sample code for detecting and redacting PII with the Apryse SDK.
This article covers FOIA and public-records redaction in two parts. The first part is the records workflow. The second part is the implementation, with working sample code. If you are here to write code, skip to Implementing FOIA redaction with the Apryse SDK.
What Has to Come Out of a Public Record
A FOIA response is a disclosure exercise, not a privacy exercise, and that difference changes how the redaction rule set is built. The question is not “what in this document is sensitive” but “what in this document falls under an exemption”. Those are not the same set.
A privacy rule set is organised by data type: find the personal identifiers, remove them. A records rule set is organised by exemption category, and the content it removes is often not personal data at all. Deliberative material, privileged communications, information affecting national security and commercial confidences can all be exempt while containing nothing that would register as PII to a pattern-matching rule.
The practical consequence is that over-redaction is a real failure mode in records work rather than a safe default. Removing more than the exemptions permit is itself a failure to disclose, and it is the kind of failure that surfaces on appeal. The goal is to remove exempt content permanently while leaving the rest of the record intact and usable, which is exactly what redaction is for.
Freedom of Information Act (FOIA) requests are designed to make government records accessible, but not every piece of information inside those records can, or should, be released. Sensitive details such as personal identifiers, national security information, or privileged communications are often embedded directly within PDFs that agencies provide. That’s where redaction becomes essential.
Redaction isn’t just about hiding text; it’s about permanently removing protected data while still delivering the rest of the document intact. Without it, agencies risk exposing private information, violating compliance requirements, or undermining public trust. For organizations responding to FOIA requests, effective redaction ensures the balance between transparency and privacy: citizens gain access to the information they’re entitled to, while sensitive content stays securely out of sight.
Reviewer Approval Before Release
In records work the review step is not optional polish, it is where the exemption decision actually gets made. A pattern can find a candidate; only a person can decide whether a given passage is exempt and under which provision.
The mechanism that makes that possible is the separation between marking and applying. Redact annotations identify the regions to be removed and stay visible, movable and re-definable for as long as you leave them unapplied. A records officer can approve a candidate, adjust its boundaries, or reject it outright. Nothing is destroyed until the apply step runs.
Applying the redaction is irreversible, which is why the approval has to sit before it rather than after. The workflow that follows from that is: automated detection produces candidates, the candidates go into a review queue, a reviewer approves or rejects each one, and only then is the redaction applied and the release copy generated. The implementation half of this article shows how to produce reviewable candidates rather than applying redactions straight away. See enterprise-grade redaction.
Audit Trail for a Records Request
Once a redaction is applied, the removed content is gone. That is the point, and it has a consequence: the record of the process is the only thing left that can demonstrate how the request was handled.
For a FOIA response that record should hold what was detected and by which rule, what the reviewer approved or rejected and on what basis, which exemption was cited for each withholding, when the redaction was applied, and what the verification check returned. The exemption basis matters more here than in a privacy workflow, because an appeal asks why something was withheld rather than whether something was missed.
It is also worth keeping the original. Redaction is irreversible, so an agency that has to re-examine a withholding on appeal needs the unredacted source document still in the system of record, with the redacted copy as a derivative. See the compliance redaction process.
Keeping Records Inside the Agency Network
Most agency environments cannot send records to a third-party service to be processed, which rules out a large part of the redaction tooling market before the evaluation starts.
The Apryse Server SDK installs on infrastructure the agency controls: on-premises, in private cloud, or fully air-gapped. Redaction requires no call to an external service, and because redaction ships in the base binary rather than as a downloadable module, there is no runtime fetch either. The records stay where they are and the processing comes to them.
If an external AI service is used for detection, as described later in this article, that is the component to scrutinise rather than the SDK: the question becomes what leaves the network to be analysed. Browser-side review on the Web SDK can also run entirely inside the network, since WebViewer renders and redacts in the browser. See on-premises and air-gapped redaction.
Redaction in Agency Case Management Platforms
Agencies rarely handle records requests in a standalone tool. The request arrives in a case management system and the documents live there, so redaction is most useful when it happens inside that workflow rather than in an export-and-reimport cycle.
Appian
Agencies running case management on Appian can handle document viewing, annotation and redaction within the case workflow, using the WebViewer plugin for the platform. See case management redaction in Appian for what the integration currently supports.
Salesforce
Agencies on Salesforce can keep FOIA request handling and redaction native to the platform, with WebViewer available as a Lightning Web Component. See FOIA request redaction in Salesforce for what the integration currently supports.
Implementing FOIA Redaction with the Apryse SDK
What follows is the implementation walkthrough, with working sample code you can download and run. The processing runs server-side on the Apryse Server SDK, in C#, with a browser-based review option covered near the end. The Redaction Package must be on the production licence key; trial keys include all packages.
In this article, we will see how we can use the Apryse SDK to search through PDFs for content that needs to be removed, then automatically redact it.
Redaction runs in two steps, and this is the part developers most often look for and miss. Redact annotations identify the content to remove and can be created interactively or programmatically through text search or text extraction. A separate apply step then destroys the text, image and vector content inside those regions. There is no single redact call that does both.
What is the Apryse SDK?
The Apryse Software Development Kit provides a powerful set of APIs to handle PDFs, DOCX files, Spreadsheets, CAD drawings, DICOM images, and more.
It ships with sample code and test files for a wide range of languages, and supports complex document workflows beyond redaction: document generation, conversion, collaborative editing and digital signatures all run on the same core. Redaction itself is an add-on and requires the Redaction Package on the licence key.
In this article, we will start with one of the samples that is shipped with the SDK, then extend it to apply redactions to a PDF.
For this article, we will be using C#, but the Apryse SDK can be used with many other languages as well, including C++, Java, and Node.JS. I will also be using version 11.7 of the SDK and Windows 11. You should get similar results on macOS and Linux.
I’m assuming that you have already downloaded the Apryse SDK and have the samples running. If you haven’t, then check out the getting started guide.
The Initial Sample Code
The Apryse SDK ships with the HighlightsTest that uses search functionality to find the location of words and creates a highlight annotation each time that the word “Federal” is found.
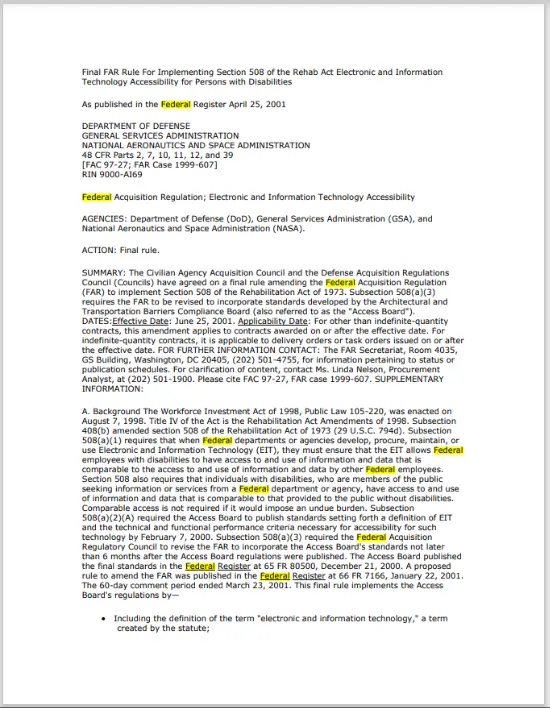
Figure 1: The result of running the Highlights Test sample - the word 'Federal' has been found and highlighted.
That’s clever in itself. But in this article, we will significantly extend the code, to find multiple search terms, and redact them, rather than highlight them.
I won’t go through all of the code here. You can download the sample code to see for yourself. The function doing most of the work is SearchAndRedact (There are also two overloads that allow you to use default options, but they then pass those arguments to this function).
The essential parts of the code are
- A PDFDoc is created from the original PDF.
- A TextSearch is created for each item in the collection of Search Items. These can be a word, a group of words or a Regex. In this case, we are including TextSearch.SearchMode.e_highlight, which means that we will get location information when a match is found as a “highlight”.
- TextSearch.Run is called iteratively until no more matches are found. If a match is found, then the return code will be TextSearch.ResultCode.e_found.
- If a match is found, then the location of the highlight is extracted. Typically, there will be 8 “quads” which, between them, mark the various corners of the highlight. However, if the result was split over a line break, then there may be multiple sets of quads for a single highlight.
- If we wanted, we could use these coordinates to add highlight annotations to the PDF (and the “Highlights Test” sample, mentioned earlier, does exactly that). In this case though, we will use that information to create a redaction object for each set of quads, the page on which it was found, and potentially any overlayText (for example “FOIA”).
- Finally, once all of the Search Items have been processed, the redactions are “applied”. The search item isn’t just obscured, it is completely, and permanently, removed from the PDF.
Phew that’s a lot of work! Thank goodness that the code does it for you.
Let’s run that code with one of the sample files that ships with the SDK (which I have included in the GitHub sample).
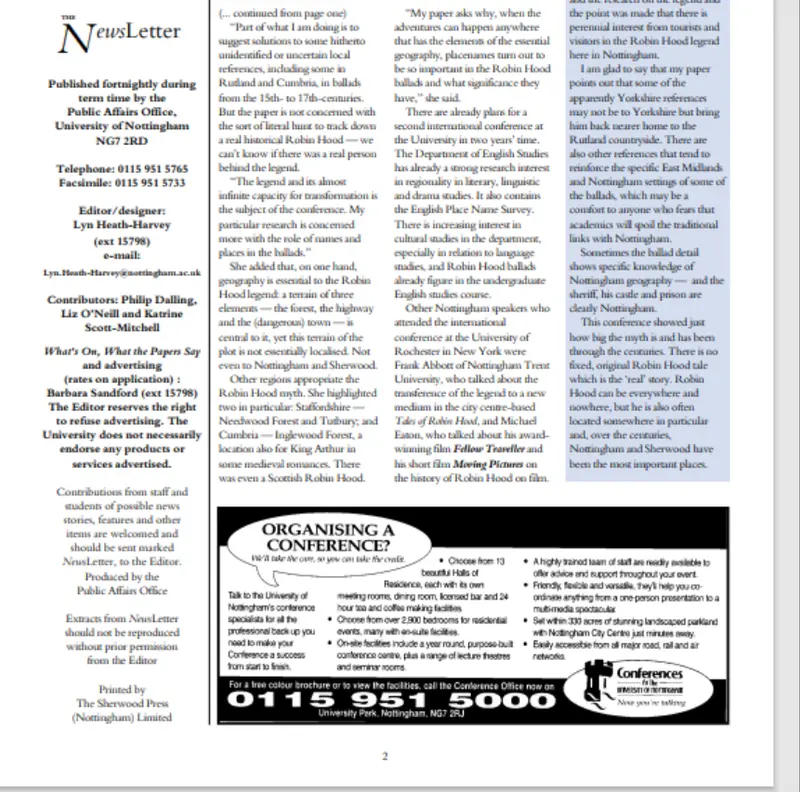
Figure 2: Page 2 of the sample document.
The document contains information relating to a conference on Robin Hood. It also has various phone numbers, email addresses and URLs.
While this is a publicly available PDF, let’s use it as a way to demonstrate redaction. You could of course run the sample with your own documents.
Let’s find and redact the phone numbers, email addresses, URLs and the words "Robin Hood”.
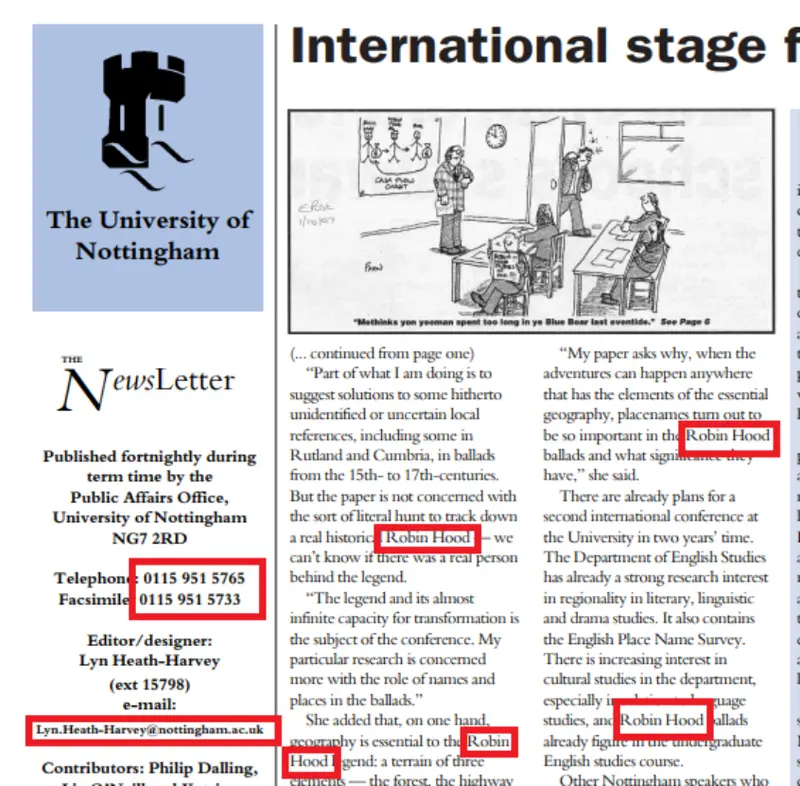
Figure 3: A zoomed in area of part of the sample PDF. There are phone numbers, email addresses, and the words 'Robin Hood" including where the name is split over two lines.
We need to set up the code to know what to search for (you could create an app that allows you to do that interactively, but for now we will hard code it).
We’ll use a mixture of Text and Regex.
Now we just need to pass the list of search items to the function that we saw earlier and run the program. We are also going to specify that we want the redactions to be black and to have “FOIA” in red written on them.
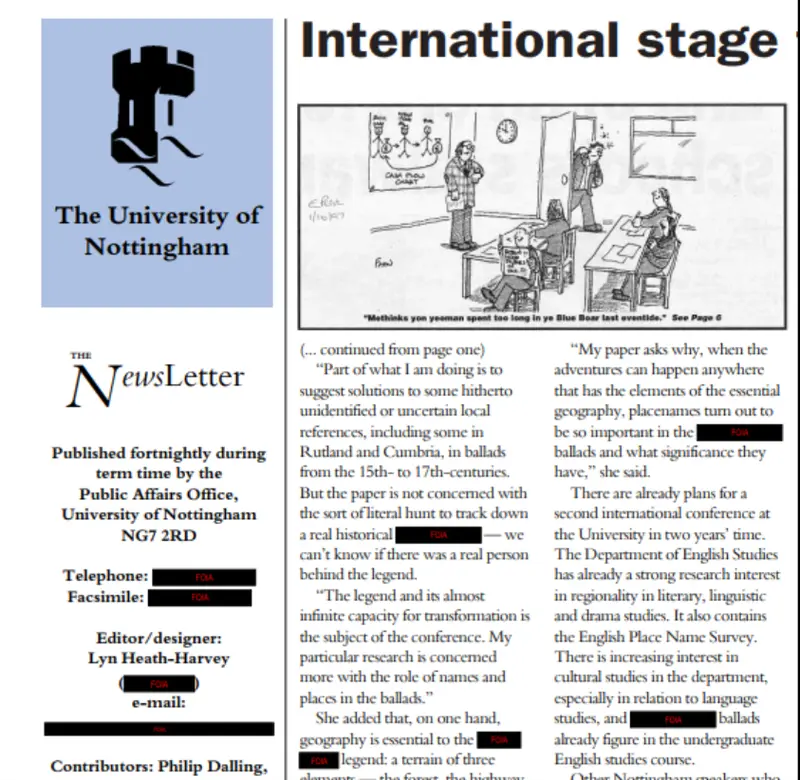
Figure 4: The result of automated search and redaction.
That’s a great result. It found all the text I had marked that needed to be redacted, including search items that were split over a line break. In fact, it did better than I did manually, it found a piece of PII that I had missed – an extension telephone number.
The Importance of Manually Reviewing Redactions
So far, we have entirely automated the process, but you could just use the Apryse SDK to identify potential text for redaction, then allow the user to manually verify them before applying them.
This is the code-level implementation of the review step described in Reviewer approval before release above. Producing annotations rather than applying redactions directly is what makes an exemption decision reviewable.
In order to do that, we need to create Redaction Annotations, rather than creating Redaction objects directly.
In this case, there is no need to call Redactor.Redact(doc, redactions, appearance), which is responsible for applying the redactions.
We can then save the Document and open it in Apryse WebViewer (You will need to set full API and enableRedactions to true in the constructor). Now it’s possible to see what has been marked for redaction, and either apply all of the redactions, remove potential redactions before the rest are applied, or even just apply individual ones.
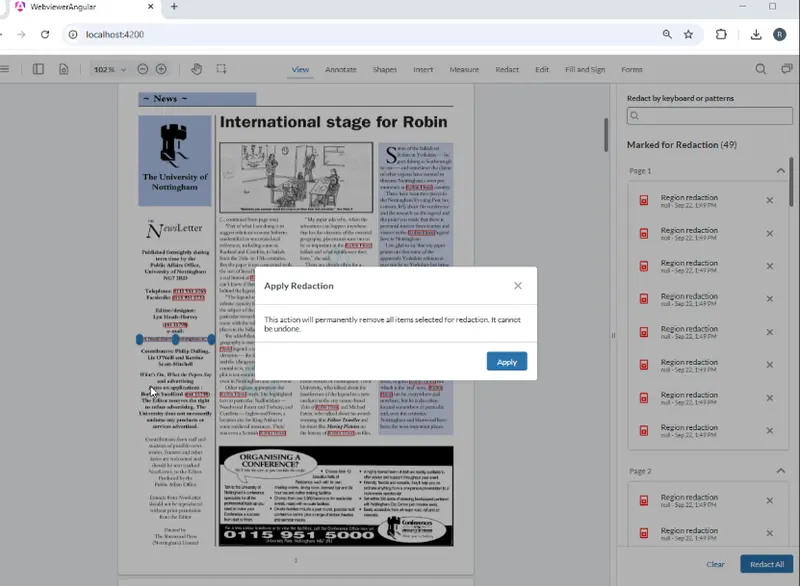
Figure 5: Our PDF within Apryse WebViewer - the user can now review what should be removed before applying the redactions.
Dealing with PII in Images
Sometimes of course, there can be an issue with information that needs to be redacted being present in an image. An extreme case would be a password that is on a Post-it note in an image.
In our example document though, there are a number of images that contain adverts. And some of these contain phone numbers, which is one of the things that we want to redact.
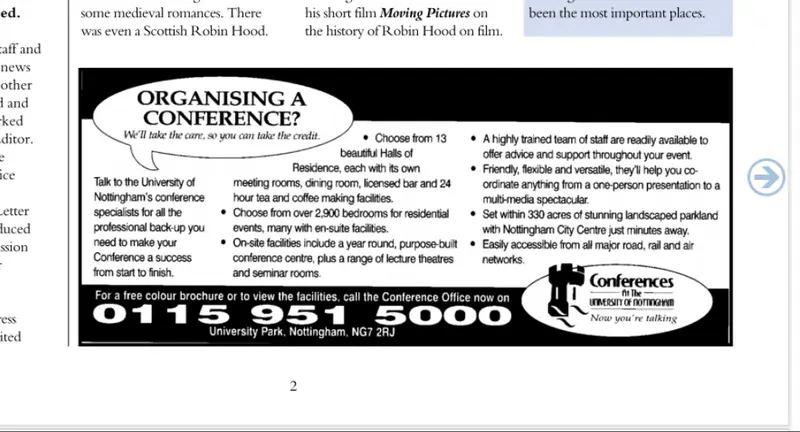
Figure 6: A possible gotcha is if there is PII within an image. Apryse has an OCR option that can be used to extract the text.
Apryse has a solution which is a natural extension of what we have been doing, the optional Apryse OCR/ICR module.
Which of the two you need depends on the document. OCR recognises printed, machine-generated characters. Handwritten entries, which are common on older agency forms and correspondence, need ICR, which recognises handwriting using neural networks. OCR and Redaction are separate Server SDK add-ons and both packages have to be on the production licence key. See redacting scanned documents.
Once that module is in place, you can use the OCR sample code to add a searchable text layer to the PDF. I won’t include the code for that, but you can find sample OCR code in the Apryse SDK Samples.
Now we can redact the modified document including things that are detected within the image.
To make it more fun, we will also redact the word “conference”. That’s easy to do, we just need to change our code slightly so that it includes that word in the list of things to search for.
Now the telephone number and most of the occurrences of the word “conference” have been redacted as well.
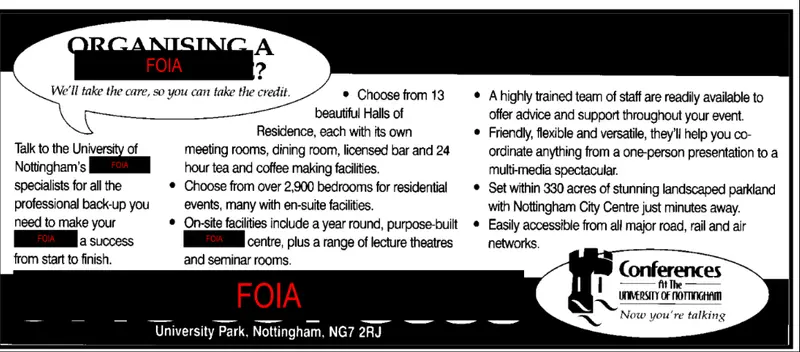
Figure 7: Having created a text layer in the PDF, it is now possible to search for PII and redact it, even if it is an image.
Note though, that there is the unredacted word “Conferences” at the bottom right of the page. This is an example of OCR being imperfect – the font is unusual enough to have not been correctly identified. This is of course, a contrived example with a very unusual font, but if you need to, though, then it is easy to manually redact that word using either Apryse WebViewer or Xodo PDF Studio.
That miss is worth dwelling on rather than moving past, because it is the single most important caveat in this article for records work. Detection runs against what OCR recognised, not against what is on the page. If recognition is incomplete, the pattern has nothing correct to match, and the identifier survives into the release copy. On a scanned archive that is a reason to route low-confidence pages to human review rather than trusting the automated pass.
Using AI to Find PII
With the rapid development of AI, you may wish to use that to identify the location of PII or other text that needs to be redacted from a document. As long as the AI returns the location of the text that needs to be removed, the code sample can be easily modified to work with that, rather than using the built in Search capabilities to identify problem text.
That’s awesome. As technology changes over time, you can continue to rely on the Apryse SDK to do the server-side processing of PDFs and other documents, while not being locked into a specific search mechanism.
Whether to use a model or a pattern is a real decision in records work rather than a matter of taste. Patterns are deterministic, repeatable and auditable: the same rule produces the same result, and you can state in an audit record which rule fired. Model-based detection generalises better to unstructured phrasing and to exemption categories that have no regular shape, but it is harder to evidence on appeal and harder to reproduce exactly.
Either way, detection only identifies candidates. Neither approach removes anything until the apply step runs, and neither removes the need for the review step. See PII detection for AI pipelines.
Can Redactions be Applied Directly from a UI?
Absolutely! Apryse WebViewer provides a mechanism where you can search and redact the contents of PDFs directly within the browser. Depending on your business requirements, that might be a good solution for you. It also has the benefit that the redaction occurs entirely within your browser with no need for the documents to be sent to a server for processing or even downloaded onto your local machine. You can check that out for yourself, right now, with the redaction demo in the WebViewer Showcase.
Two constructor properties are required to enable it: both fullAPI: true and enableRedaction: true must be set, and Full API alone is not sufficient. All redaction operations wait for the documentLoaded event.
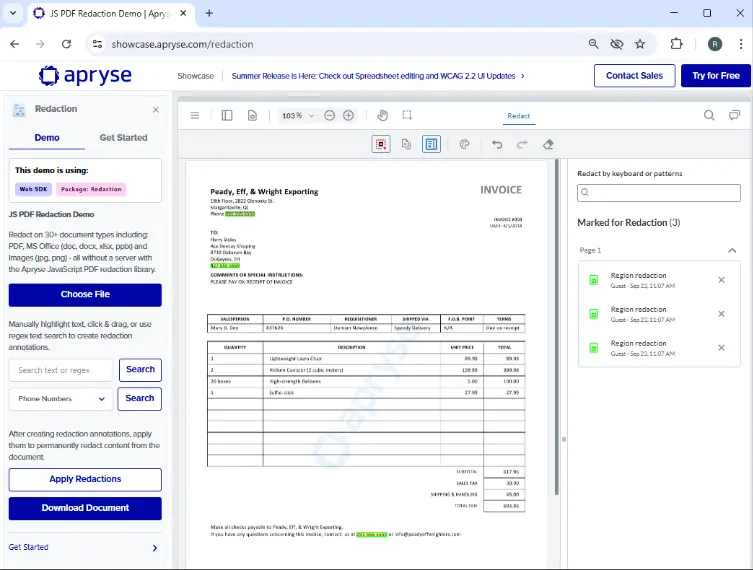
Figure 8: The redaction demo in the Apryse Showcase, showing how you can interactively search for text in a PDF.
Document Security Across the Records Lifecycle
Redaction is one control among several, and it is not the right control at every stage of a record’s life. At intake and in storage, access control and encryption are what protect a record: both restrict who can reach content that is still present in the file, and both are reversible by design, because an authorised user has to be able to read the document.
At the release step that logic inverts. A released record is outside the agency’s control, and no permission setting travels with it. Restricting access to content that remains in the file is not sufficient when the file itself is leaving, which is why removal rather than restriction is the right mechanism at that point.
Two operations are involved at release, not one. Redaction removes the visible exempt content. Sanitization removes hidden non-visual data such as metadata, embedded scripts, form data and hidden layers, and it is in the base Server SDK package. A release copy that has been redacted but not sanitized can still carry document properties, revision history or form data that the exemption was meant to withhold. See redaction versus sanitization and PDF sanitization.
Frequently Asked Questions
What tools do government agencies use to redact documents for FOIA requests at scale?
Agencies generally redact with software that runs inside their own environment rather than a hosted service, because records cannot be sent outside the network. A server-side SDK handles detection and removal headlessly across a request backlog, with a browser-based review step where a records officer approves candidates before anything is applied.
Can AI find and redact personal information in FOIA responses without sending records outside our agency’s network?
Yes, provided the detection runs inside your environment. The Apryse Server SDK installs on infrastructure you control, on-premises, in private cloud or air-gapped, and redaction requires no call to an external service. If an external model is used for detection, that is the component to scrutinise, since the SDK itself does not need outbound access.
How is redaction for FOIA different from redaction for privacy?
The rule set is organised differently. A privacy rule set asks what personal data is present. A FOIA rule set asks what falls under an exemption, which can include material that is not personal data at all. That is also why over-redaction is a failure mode in records work rather than a safe default.
Can a records officer review redactions before they are applied?
Yes, and in records work this is the normal pattern. Redact annotations mark candidate content and stay visible, movable and re-definable until the apply step runs, so a reviewer approves first. Applying the redaction destroys the content permanently.
What should the audit trail record for a redacted FOIA response?
What was detected and by which rule, what the reviewer approved or rejected and under which exemption, when the redaction was applied, and the verification result. Because the removed content is destroyed by design, that record is the only remaining evidence of how the request was handled if the response is appealed.
Can we redact scanned records that have no text layer?
Not directly. A scan has no text for a pattern to match against, so it goes through OCR first and detection runs against the recognised text. Handwritten entries need ICR rather than OCR. Both OCR and Redaction are Server SDK add-ons and both packages must be on the licence key.
Does redaction remove a document’s metadata as well?
No. Redaction removes visible page content. Metadata, embedded scripts, form data and hidden layers are removed by sanitization, which is in the base Server SDK package. A released record should usually have both run against it.
Can redaction run inside Appian or Salesforce case management?
Document viewing, annotation and redaction can be handled within the case workflow on both platforms rather than exporting records to a separate tool. See the platform integration articles linked above for what each one currently supports.
Where Next?
If you are implementing: get a trial licence key and download the code from the GitHub sample. There is a lot more the Apryse SDK can do, and plenty of documentation to get you moving quickly. No credit card required.
If you are evaluating: see redaction use cases by industry for how other regulated sectors handle the same problem, and enterprise-grade redaction for the capability, review and audit layer in one place.
For in-browser review, Start a Free Trial (Web SDK).
There’s also a support channel if you have any questions.