Josh Coffey
Chief Technology Officer
Published July 20, 2023
Updated November 06, 2026

5 min


Extract PDF Data in Node.js: Tables, Fields and JSON
Josh Coffey
Chief Technology Officer
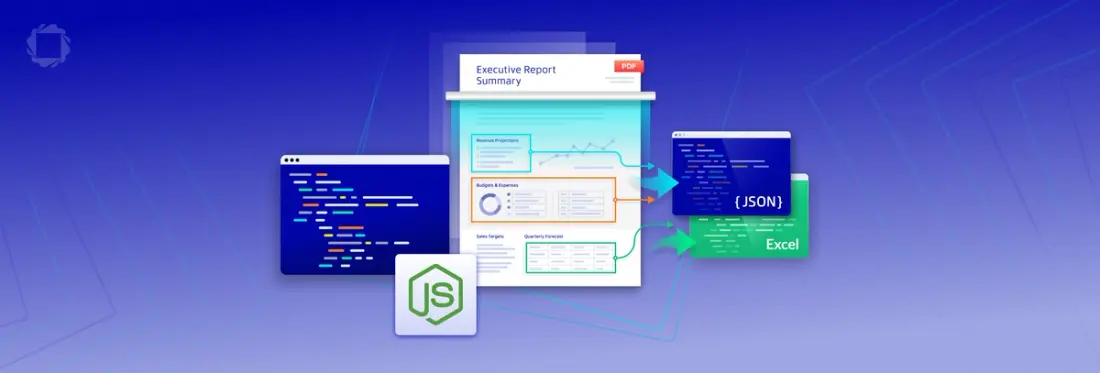
To extract structured data from a PDF in Node.js with Apryse, you install the SDK and the Smart Data Extraction module from npm, initialize with your license key, pass a file path and an extraction engine, and get back JSON. The engines return tables, document structure with position data, form fields, or key-value pairs.
Three things catch people out. The extraction capabilities ship as an add-on module, so a base SDK install alone will not run them. PDFNet.initialize() must be called before any extraction call, and in Node, PDFNet.runWithCleanup() wraps that initialization, so every extraction call runs inside its callback. And the native binaries are platform-specific, so extraction runs on Windows and Linux x64 only, not on macOS or Arm. The complete working example below runs against a scanned and a digital PDF and prints the returned JSON.
This post covers Apryse Server SDK integration using Node.js on Windows and Linux (x64), extracting form fields from scanned and digital PDFs as JSON. Tables, document structure, key-value pairs, and classification use the same call with a different engine option, and short excerpts for tables and document structure appear near the end. For text extraction, see Text Extraction. For other languages or platforms, see the Server SDK get-started guide.
Why PDFs Store Characters, Not Structure
A PDF records characters at coordinates on a page. It does not record which characters form a table cell, a heading, or a form field. Tagged files, such as PDF/UA documents, carry structure. An untagged invoice, purchase order, or report has no structure to read, and a scanned one has no text layer at all.
Text extraction and structured data extraction are different jobs. Text extraction returns characters in reading order. Structured extraction returns what those characters mean on the page: a table with merged cells, a key with its value, or a form field with a type and a bounding box.
The Smart Data Extraction add-on for the Server SDK runs inside your Node.js process. There is no HTTP round-trip and no document data leaving your environment. The JSON it returns carries page numbers and bounding boxes, so your app can load it into a database, draw it on a review screen, or pass it to a model as structured input.
Prerequisites
This guide assumes you have a Node.js environment set up. Use Node.js 10.x through 24.x. Smart Data Extraction runs on Windows and Linux (x64). macOS, Arm, and 32-bit are not supported.
Apryse Server SDK Trial Key
If you don't already have an Apryse account, go to https://dev.apryse.com and register a new account with Apryse. This allows Apryse to grant you a demo license key which will be used with the Apryse Server SDK to enable demo functionality.
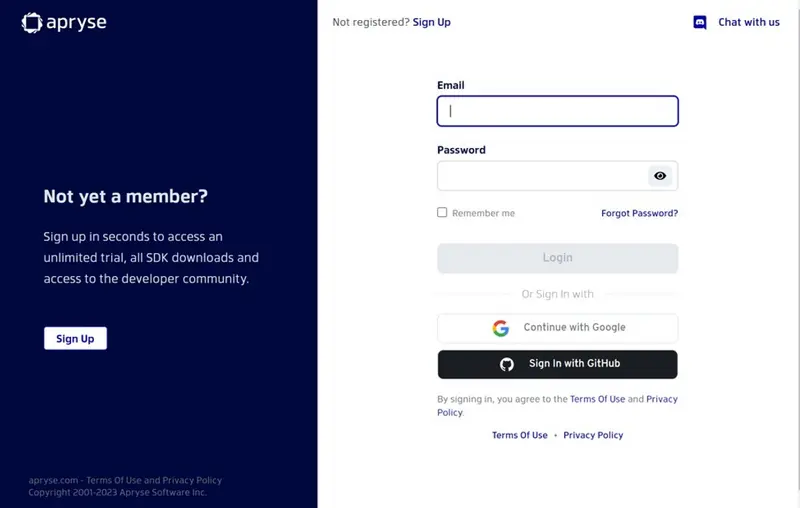
Developer Portal
Log into https://dev.apryse.com with your registered account. For this guide, you’ll be developing a Node.js application, so select Windows or Linux as your development OS.
Below the Platform selection is a blurred field with your unique developer trial key. Click Reveal to show the key. Copy and paste the key into a text file. You need it later to run the code.
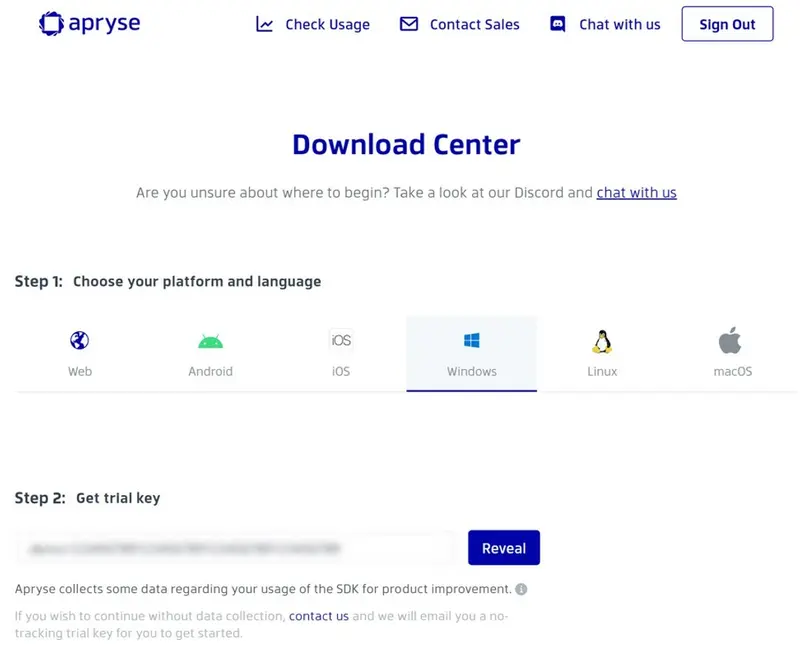
Download Center Platform and Trial Key
Install the Packages
Install the Server SDK and the extraction module together. The npm path covers Windows and Linux x64. macOS, Arm, and 32-bit are not supported for this module.
# Install the Server SDK and the Smart Data Extraction module
npm i @pdftron/pdfnet-node @pdftron/data-extraction
This feature requires the Smart Data Extraction add-on module, which is a separate download from the base Server SDK. On npm, that module is @pdftron/data-extraction. See the modules documentation for other installation options.
License keys are confidential. Do not commit them to public repositories. Use environment variables or a secrets manager to inject your key at runtime.
Run a Complete Node.js Example
The script below checks that the module is present, then runs the form field engine on each file and prints the JSON string it returns. Replace the two file paths with your own PDFs.
# Run the extraction script with Node.js
node ExtractIntakeFormFields.js
runWithCleanup initializes PDFNet with your key, runs the function, and releases resources when it finishes. The shutdown call in the final then block lets the Node process exit. Because the module installed from npm, the script needs no resource search path call.
To extract something other than form fields, swap the engine option. The docs list e_Tabular, e_DocStructure, e_GenericKeyValue, and e_DocClassification alongside e_Form. For tables as a spreadsheet, extractToXLSX writes an Excel file directly.
Expected Output
Each call returns a JSON string. This is the shape of the output, trimmed to two fields:
Each entry in formElements has a type, a confidence between 0.0 and 1.0, and a rect in the form [left, top, right, bottom]. In the PDF coordinate system the origin is the bottom left corner of the page and units are PDF points.
Other Extraction Engines for PDF Data Extraction
The Smart Data Extraction module has five engines: tabular, document structure, form fields, key-value, and document classification. The excerpts below cover the first three. They come from the DataExtractionTest sample, assume you have defined inputPath and outputPath, and are fragments, not standalone scripts.
Extracting Tabular Data
The tabular engine converts PDFs that contain tables into tabular JSON or an Excel XLSX file. It converts all content in the PDF, so non-tabular data such as paragraphs is included in the output. Remove that data after conversion if you don’t need it.
Document Structure Conversion
The document structure engine converts a PDF into JSON that describes the file in its entirety. The JSON contains an element for every item in the PDF, such as text, images, graphics, and tables. Each element has its position data and text formatting.
Extracting Form Fields
The form field engine uses an AI-based algorithm to produce JSON that describes the location and type of each detected form field. It detects fields in native PDF forms, flat non-interactive PDFs, and scanned image-based documents.
Production Considerations
- Trial output is capped and altered: In trial mode, output is limited to 100 pages, and a random evaluation page is inserted into the output. Do not load trial output into downstream systems, and do not compare it page for page against licensed runs.
- Platform support is narrow: Extraction runs on Windows and Linux x64. Container images built for Arm and development machines on macOS cannot run this module, so test in a Linux or Windows x64 environment.
- Password-protected PDFs need the password: Create a DataExtractionOptions object, call setPDFPassword with the password, and pass the object as the last argument to the extraction call. Without it, the module cannot open a password-protected file.
- Low-quality scans produce low-confidence fields: Read the confidence value on each formElements entry and send entries below your own threshold to human review in your app.
- An archive install needs a search path: If you install the module from the Windows or Linux archive instead of npm, call PDFNet.addResourceSearchPath() with the parent Lib folder, not the Windows or Linux subfolder, before the isModuleAvailable check.
What to Test
- Field positions: Draw each rect on a rendered copy of the page and compare it with the form. Read coordinateSystem first. A value of “PDF” puts the origin at the bottom left, and “originTop” puts it at the top left.
- Low-confidence entries: Sort formElements by confidence and check the lowest ten against the page image. Fields that look wrong here show you where your threshold belongs.
- Scanned and digital parity: Run both versions of the same form and compare field counts and types. A mismatch is a signal to inspect the scan first.
- Trial page insertion: Trial runs insert an evaluation page into the output. Compare the pageNumber values with the input PDF’s page count and set aside any page that has no counterpart in the input.
- Field types: Check a known form that mixes checkboxes and radio buttons, and confirm the type values are formCheckBox and formRadioButton where you expect them.
Getting Started
Install both packages with npm i @pdftron/pdfnet-node @pdftron/data-extraction. Get your free trial key at dev.apryse.com before running the code. For the Node.js setup path, see the Node.js get-started guide. For engine options and JSON specifications, see the Smart Data Extraction workflow guide. The multi-engine sample is the DataExtractionTest sample.