Josh Coffey
Chief Technology Officer
Published July 20, 2023
Updated November 06, 2026

5 min


PDF Data Extraction in Python: Tables, Key-Value Pairs, and Form Fields
Josh Coffey
Chief Technology Officer
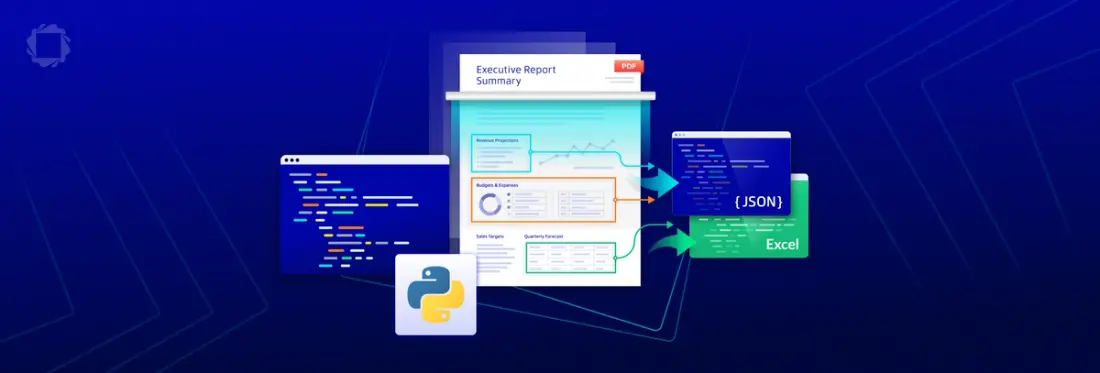
To extract structured data from a PDF in Python with Apryse, install the SDK and the Smart Data Extraction add-on, initialize PDFNet with your license key, call ExtractData with the engine you need, and read the JSON it returns. The engines cover key-value pairs, tables, document structure, and form fields. Every result carries page numbers and bounding boxes. Three things catch developers out.
Smart Data Extraction ships as a separate add-on module, so a base SDK install does not run it. PDFNet.Initialize() must run before any extraction call, or the call fails. And extraction runs on Windows and Linux (x64) only. pip installs both packages there, and macOS is not supported. The complete example below prints the returned JSON.
This post covers Apryse Server SDK integration using Python 3 on Windows and Linux (x64). It shows how to extract key-value pairs, tables, document structure, and form fields from PDFs as JSON, and how to export tables to XLSX. It does not cover macOS, which Smart Data Extraction does not support, or reading plain text with the base SDK; for that, see Text Extraction. For other languages or platforms, see the Server SDK get-started guide.
Why Plain PDF Text Extraction Loses Tables, Fields, and Structure
PDF was built as an output format. It stores glyphs at page coordinates, so a table is a set of positioned strings and lines, not rows and cells. Unless the file carries structure tags, as PDF/UA files do, nothing in it says which text is a header or which value belongs to a label.
That gap hurts intake workflows. Your users upload invoices, claim forms, financial statements, and ID documents, and your app needs the data in a database, not a page image. Template rules break when layouts vary by sender. In financial services, insurance, and healthcare, sending those documents to a third-party extraction API is often not an option.
Smart Data Extraction is a Server SDK add-on module that runs on your own server, so document data stays in your environment. It returns JSON with page numbers and bounding boxes. Your app can use that JSON to validate fields, draw overlays on the source page, or feed an LLM or RAG pipeline with structured input instead of a text blob.
Two distinctions matter before you pick an engine. Text extraction returns the characters on a page. Smart Data Extraction returns labeled structure. Within the module, the tabular engine focuses on cells, financial tables, and numeric data, while the document structure engine reconstructs how the page looks: indentation, spacing, alignment, and borders.
Running Smart Data Extraction in Python: Install, Initialize, Extract
The implementation takes three steps. Install two packages from pypi.apryse.com, initialize PDFNet with your license key, and call ExtractData with the engine you need. The base package is apryse-sdk. The extraction module is apryse-data-extraction, and it installs on Windows and Linux x64 only.
This feature requires the Smart Data Extraction add-on module, which is a separate download from the base Server SDK. With pip, the second command below installs it. See the modules documentation for download and installation instructions.
# Install the base SDK and the Smart Data Extraction module (Windows or Linux, x64)
pip install apryse-sdk --extra-index-url=https://pypi.apryse.com
pip install --extra-index-url=https://pypi.apryse.com apryse-data-extraction
License keys are confidential. Do not commit them to public repositories. Use environment variables or a secrets manager to inject your key at runtime.
Set APRYSE_LICENSE_KEY to your trial key, then save the following as extract_claim_data.py and run it with python3 extract_claim_data.py.
IsModuleAvailable checks the add-on before extraction runs. ExtractData takes a file path and an engine and returns a JSON string, which json.loads turns into a dictionary. Because you installed through pip, you can skip PDFNet.AddResourceSearchPath. The finally block calls PDFNet.Terminate() so resources release even when extraction fails.
Returned JSON (synthetic data, trimmed to the fields discussed)
The values above are illustrative. Each pair carries the key text, the value text, bounding boxes for both, per-word boxes, and a confidence score. The Member ID pair scores 0.71 against 0.94 for the date of birth, which is the signal your app uses to route a pair to review.
The same call covers the other capabilities. To extract tables from PDF in Python, change the engine. For Excel output, switch to ExtractToXLSX. Pass an output path as the second argument to ExtractData to write JSON to a file instead of returning a string.
What You Need | Call | Returns |
|---|---|---|
Extract tables from PDF in Python |
| JSON string of table content |
PDF to JSON in Python (full structure) |
| JSON string with an element for every text, image, graphic, and table item, with position and formatting |
Extract form fields from PDF in Python |
| JSON string with the location and type of each detected form field |
PDF to Excel in Python (table export) |
| XLSX file of the tabular result |
Production Considerations for Extraction Workers
Initialize once per worker: PDFNet.Initialize() is a once-per-process call. In a long-running worker, run it at startup and leave PDFNet initialized while the worker handles documents. Call PDFNet.Terminate() at shutdown, not after each file.
Check each engine at startup: A missing add-on module surfaces as a failed extraction at runtime. Call IsModuleAvailable for every engine your worker uses, and fail the deploy instead of the first customer document.
Flip the y-axis before overlaying boxes: Extraction reports bounding boxes from the top left of the page. PDF annotation coordinates start at the bottom left. Subtract the y values from the page height before you draw highlights on the source page.
Treat confidence as input to your review rule: Key-value pairs and form fields return a confidence score. Table results do not. Set a threshold per document type in your app and route pairs below it to a person. For tables, check row totals against the source instead.
Expect the whole page in tabular output: The tabular engine converts all content in the PDF, so paragraphs appear in the JSON and the XLSX. Filter non-table content after extraction. ExtractToXLSX exports table data. If you need layout-preserving, editable Excel from a PDF, use the Structured Output Module instead.
What to Test Before You Trust the Output
- Key and value pairing: Draw each key and value
recton a rendered image of the page and compare against the source. Run this on a sample from every sender layout you accept. - Confidence threshold: Export the confidence scores for a hand-labeled sample, find the score below which pairs are wrong, and set your review threshold there.
- Table fidelity: Open the XLSX from
ExtractToXLSXbeside the source PDF. Check merged cells, multi-row headers, and the totals row. - Trial output: Trial keys can add an evaluation message to JSON or Excel output and limit extraction to 100 pages per operation. Search trial output for that message before you compare it with production results.
Where Extraction Fits Before Your Model
Smart Data Extraction sits between document intake and your own logic. Run OCR or Redaction first when the input needs cleaning, extract next, then pass the JSON to your validation step, your database, or your LLM pipeline. Your app owns routing and storage. The module returns the structured JSON.
Getting Started with Smart Data Extraction in Python
Install both packages with pip install apryse-sdk --extra-index-url=https://pypi.apryse.com and pip install --extra-index-url=https://pypi.apryse.com apryse-data-extraction.
Get your free trial key at dev.apryse.com before running the code. See the Python guide for setup, and for password, page range, and OCR language options, see the documentation. More runnable samples are also available.
Suggested Reads: Data Extraction Using C# , Data Extraction Using Java