John Chow
Product Manager
Published June 20, 2023
Updated November 06, 2026

5 min


How to Extract Data from PDF in Java with Apryse Smart Data Extraction
John Chow
Product Manager
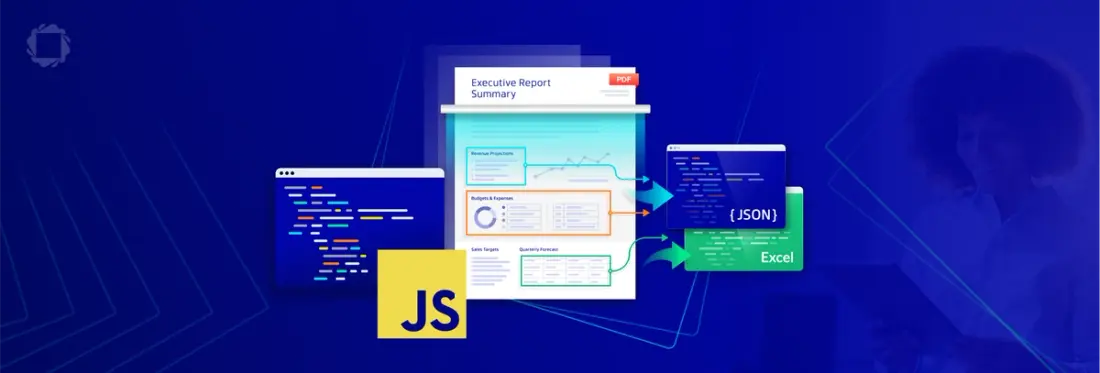
To extract structured data from a PDF in Java with Apryse, add the Server SDK and the Smart Data Extraction module to your Maven build, initialize PDFNet with your license key, call DataExtractionModule.extractData with an engine for tables, document structure, form fields, or key-value pairs, and read the JSON it returns.
Three things catch people out. Smart Data Extraction is an add-on module, so the base SDK alone will not run it. PDFNet.initialize() must run before any extraction call. The module installs through a platform-specific Maven artifact, DataExtractionModuleWindows or DataExtractionModuleLinux, for x64 only. macOS is not supported. The complete example below runs the form field engine against a scanned PDF and a digital PDF and prints the returned JSON.
This post covers Apryse Server SDK integration using Java on Windows and Linux (x64), with the Smart Data Extraction form field engine on a scanned and a digital PDF. macOS is not supported for this module. For generic programmatic and server-side text extraction, see Text Extraction. For other languages or platforms, see the Server SDK get-started guide.
Why Text Extraction Alone Misses Fields in Scanned Forms
A scanned intake form holds a page image and no text. Text extraction returns nothing for it until something recognizes the characters and the boxes around them. A digital PDF has the opposite problem: its text sits on the page as characters at coordinates, with no label that says which box is a text field and which is a checkbox.
The PDF format was designed to function as an output format for the reliable display of documents, regardless of the user’s computer or operating system. Its ubiquity means it has become one of the most widely used formats for the exchange of business documents, although accessing the data contained within them can be challenging. In structured document formats such as HTML, XML, or JSON, content can be meaningfully labeled using markup, making the task of data extraction easy.
Since PDF was designed first and foremost to be a human-readable format, many documents contain no structure at all, making extracting and processing data extremely difficult. Text content may not even be stored as words but simply as characters located somewhere on the page. While the PDF format does allow for the creation of structured documents (e.g., Tagged PDF or the PDF/A and PDF/UA standards), many documents are likely to pose problems.
The Apryse Smart Data Extraction add-on recognizes that content and returns it as structured JSON or Excel data for reuse.
Watch this exclusive webinar to see how Apryse Smart Data Extraction turns PDF content into structured data.
The distinction that matters is base extraction versus Smart Data Extraction. Base Server SDK extraction returns Unicode text, low-level text, images, and fonts. The Smart Data Extraction add-on returns structured JSON with page numbers and bounding boxes for tables, document structure, form fields, and key-value pairs. Patient intake, onboarding, and claims forms need the second kind of output.
The module runs inside your Java process on your own servers. No document data leaves your environment. Each detected form field carries a confidence score, so your code decides which detections to trust and which to route for review. That JSON is structured input for your analytics and AI pipelines.
Extracting Form Fields from Scanned and Digital PDFs in Java
This feature requires the Smart Data Extraction add-on module, which is a separate download from the base Server SDK. See the modules documentation for download and installation instructions. You need JDK 25 (LTS) and Maven. The Maven path below skips the addResourceSearchPath setup that manual archive installs need.
Start with the dependencies. Use DataExtractionModuleWindows on Windows and DataExtractionModuleLinux on Linux.
License keys are confidential. Do not commit them to public repositories. Use environment variables or a secrets manager to inject your key at runtime. The class below reads the key from APRYSE_LICENSE_KEY. Put it in src/main/java/com/example/extraction/FormFieldExtractionService.java and replace the two file names with your own PDFs.
Run it from the project root with Maven.
extractData returns the JSON as a string. Pass an output path as the second argument to write a file instead. The sample output below shows the shape for the scanned file, trimmed to the pages array. Each form element has a type, a confidence between 0.0 and 1.0, and a rect of [left, top, right, bottom]. Page numbers are 1-based. The digital file returns the same structure.
Trial keys limit output to 100 pages and insert a random evaluation page into the output. The page limit lifts with a licensed key.
Production Considerations
- Initialize once per process: Call
PDFNet.initialize()at application startup, not inside a request handler. A web service that initializes per request repeats setup work on every call. - Check module availability at startup:
isModuleAvailablereturns false when the module is missing. For a manual archive install, callPDFNet.addResourceSearchPath()with the parentLibfolder, not theWindowsorLinuxsubfolder inside it. - Check the Linux base image: The form field engines require GLIBC 2.31 or newer, such as Debian 11 or Ubuntu 20.04. A slimmer base image with an older GLIBC fails at extraction time, not at build time.
- Set the OCR language for non-English scans: The default is English. For a scanned form in French and Spanish, create a
DataExtractionOptions, callsetLanguage("fra spa"), and pass it as the last argument toextractData. - Handle externally sourced PDFs: An encrypted PDF needs
setPDFPasswordon the options object. A 300-page upload needssetPages("1-5")if you only need the cover forms.
What to Test
- Field count per page: Run
DataExtractionModule.detectAndAddFormFieldsToPDFon the same file, save the result, and open it in a viewer. Compare the added fields against the form by eye. A missed checkbox still produces valid JSON. - Confidence against your documents: Print the
confidenceof every element for a sample of your real forms, and set your cutoff from that spread. Review low-scoring elements by hand before you trust the cutoff. - Scanned against digital parity: Run the scanned and digital versions of the same form. The
typecounts per page should match. A difference points to a detection gap on one input. - Bounding box placement: Draw each
recton a rendered page and confirm it sits on the field. Repeat on a rotated page, where a swappedtopandbottomshifts every box.
Getting Started
Install with Maven using groupId com.pdftron and artifact DataExtractionModuleWindows or DataExtractionModuleLinux. Get your free trial key at dev.apryse.com before running the code. For project setup, see the Java get-started guide. For the other engines, see the Smart Data Extraction guide. The full Java sample is available in the docs.
Suggested Read: Learn how to extract data from PDF in C# using .NET