Vimal Cherangattu
Published July 04, 2025
Updated November 06, 2026

5 min


The IDP Pipeline Explained: From Raw Documents to Real Intelligence
Vimal Cherangattu
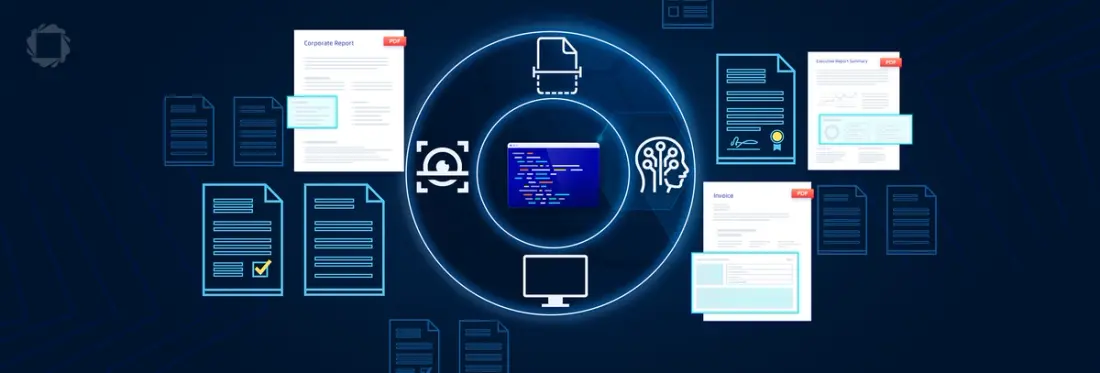
Apryse Smart Data Extraction pairs a deterministic structure foundation with purpose-built AI. It is a modular set of utilities you call from your own application, and it is the extraction engine inside an IDP pipeline you build. It needs no templates and runs in your own environment.
Intelligent Document Processing (IDP) rtakes documents past OCR. It turns contracts, invoices, forms and reports into structured, searchable data that automation, search and AI systems can read. For a deeper look at how modern extraction goes beyond traditional OCR, see Smart Data Extraction beyond OCR. The goal is structured input for your own automation, search and AI features.
But IDP isn’t one tool or product. It’s a complex workflow with a variety of pieces, and knowing what each layer does is critical to building a system that performs reliably and scales with your needs.
In this post, we’ll break down what the modern IDP pipeline looks like, which components are essential, where the market is headed, and where Apryse’s Smart Data Extraction fits into it.
What Is Intelligent Data Extraction?
Intelligent data extraction reads structured values out of unstructured documents. Smart Data Extraction first recovers each document's structure: reading order, headings, tables and layout. Purpose-built AI then classifies pages and extracts key-value pairs, tables and form fields. Intelligent document extraction applies the same process to every page. Apryse is the engine inside an IDP pipeline you build.
What Is IDP, Really?
IDP stands for Intelligent Document Processing, and at its core, it refers to using technologies like OCR, machine learning, and natural language processing (NLP) to extract, understand, and process data from documents.
This isn’t about just “scanning PDFs.” It’s about feeding downstream systems (like automation tools, databases, and AI models) with structured, labeled data that is locked in PDFs, DOCX, scanned forms, or multi-page reports.
The Market Is Growing Fast
According to Grand View Research, the global IDP market was valued at $2.3 billion in 2024 and is projected to grow at a CAGR of 33.1%, reaching $12.35 billion by 2030.
What’s driving this?
- The rise of AI models
- The cost of manual data entry and review
- Growing compliance requirements
- Demand for automation that holds up in production
The Core Components of an IDP Pipeline
An IDP pipeline runs five stages: capture, classify, extract, validate and integrate. Apryse covers parts of the first three. Validation and integration stay in your application.
1. Capture and Pre-Processing
This stage prepares documents for extraction and AI by handling:
- Deskewing
- Rotation correction
- Noise reduction
- Multi-column layout handling
- Format normalization
- Page splitting & merging
Where Apryse fits: OCR and Handwriting ICR for scanned pages, both separate add-on modules for the Server SDK.
2. Classify
The system identifies what kind of document it is, an invoice, contract, receipt, ID, claim form, etc., using AI-powered models. Apryse Document Classification, available within Smart Data Extraction, sorts pages into 24 categories and returns a page-level confidence score. Your app routes each page by type and confidence.
3. Extract
This is the heart of the pipeline, and it is two jobs. Structure recovery finds the document's geometry: reading order, headings, tables and layout. Interpretation reads meaning off that structure.
Smart Data Extraction goes beyond traditional OCR by identifying:
- Layout structure recognition, including headers, sections, zones
- Key-value pairs
- Tables, including merged cells
- Form field detection
Instead of dumping raw text, it returns JSON with page numbers and bounding boxes. Tables export to Excel and XML, and document structure exports to Markdown for LLM and RAG pipelines. That gives your pipeline structured, labeled input for AI models, search and document-driven features.
Where Apryse fits: the extraction engine. Smart Data Extraction provides the building blocks for an IDP workflow you build, starting with structure recovery, then key-value pairs, tables and form fields.
4. Validate
This stage ensures the extracted data is accurate, complete, and consistent before it flows into downstream systems. It often combines:
- Rule-based checks (e.g., field formats, totals, or logic rules)
- Confidence scoring from AI models
- Manual review via human-in-the-loop workflows for edge cases or exceptions
By blending automation with human oversight, this step catches errors before they reach downstream systems, which matters most in regulated or high-stakes work.
Validation is not Apryse's layer. Smart Data Extraction returns confidence scores for classification, key-value pairs and form fields, and your rules or your review step act on them. Smart Data Extraction is not a workflow engine.
5. Integrate
Finally, the structured data feeds into downstream systems: CRMs, ERPs, RPA bots, search engines, or AI models. In AI pipelines, this data is often used for LLM training, RAG (retrieval-augmented generation), or summary generation. Integration is not Apryse's layer. Structured JSON, Excel or Markdown feeds your systems. For the RAG case, see RAG and LLM pipelines.
The Role of Smart Data Extraction in the Document Processing Pipeline
Apryse Smart Data Extraction turns unstructured files into structured, labeled data that AI and automation systems can use.
Scanned pages go through OCR, and handwriting through ICR, before extraction runs.
Structure recovery comes first. The SDK recovers reading order, headings, tables and layout from the document's geometry. The same file returns the same structure on every run, which makes downstream results repeatable enough to regression-test.
Next, Document Classification identifies the type of document such as an invoice, receipt, ID, or contract, assigning each page a category and confidence score. Your app decides how each page flows next: extraction, human review or another process.
With structure recovered, purpose-built models read key-value pairs and table data off it, with no templates.
It is a self-hosted SDK, so documents are processed inside your own environment. It runs on an on-premise server, in a cloud VM or in a container, and offline with a license configured for it, on Windows and Linux, x64 only. Outputs are JSON, Excel and XML for tables, and Markdown for document structure.
It’s the structured data layer that feeds AI pipelines, RPA tools, and document-driven products.
What Changes When Extraction Runs in Your Environment
If you build document features, you need control over where documents go and what the pipeline does with them. Apryse Smart Data Extraction gives you:
- Deployment inside your own infrastructure: on-premise server, cloud VM or container
- No call to a third-party extraction service
- Document data that stays inside your environment
- Structured JSON, with Markdown for LLM and RAG input
Whether you're automating invoice processing or training a domain-specific AI model, secure and reliable data extraction is non-negotiable.
The Future of IDP Is Modular
The IDP landscape is shifting toward modular, composable stacks, not monoliths. Teams are assembling workflows from separate tools for each layer:
- Smart Data Extraction to structure content and classify documents
- A rules engine or AI validator to check the output
- An RPA tool or agentic workflow to act on the output
That shift gives teams the flexibility to swap any single layer without rebuilding the pipeline around it. Apryse's role in that stack is the layer underneath the others: turning messy documents into structured, labeled data the rest of the pipeline can use.
Ready to try it? Contact Sales or Start Your Free Trial to run Smart Data Extraction on your own documents.