Tabinda Khan
Senior Product Marketing Manager
Published October 07, 2026
Updated October 13, 2026

5 min


What Gets Lost Between the PDF and the Prompt
Tabinda Khan
Senior Product Marketing Manager
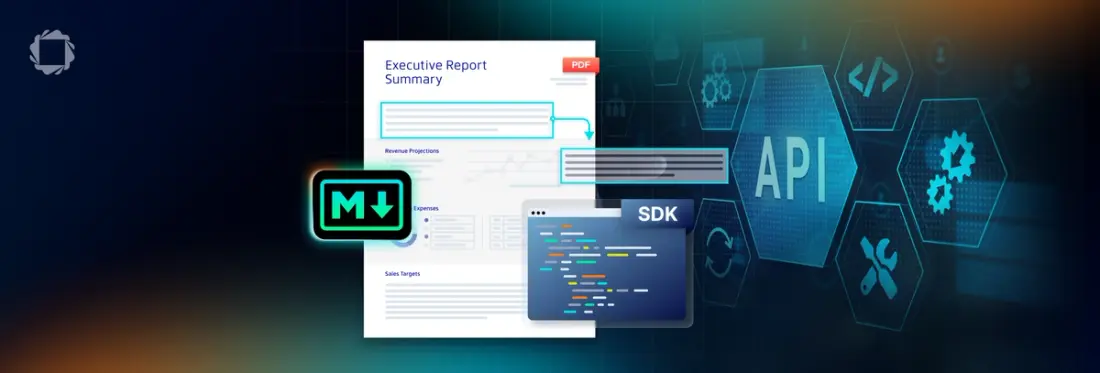
Headings, tables, and reading order rarely survive the trip. Smart Data Extraction now outputs Markdown built from document structure, so they do.
Trace one sentence through a retrieval pipeline and you can watch the context fall away.
In a PDF, a sentence has useful structure around it. There may be a heading above it. A table row border around it. The page may have a document footer. When the words are flattened to plain text, that context disappears. AI pipelines split content into retrieval-ready chunks, and group the sentence with unrelated text instead of the section it belongs to. By the time it reaches the prompt, the words are intact, but the document meaning is not.
The model will read that fragment and answer fluently, except it answers something slightly different from what you asked.
Nothing in that chain threw an error. Every character was read correctly. What was lost was everything around the characters, and almost all of it was lost at the first step.
This release is about that step.
Markdown Is Now a Smart Data Extraction Output
Smart Data Extraction now includes a single API for extracting documents directly to Markdown, following the same pattern as the existing ExtractTo APIs for structured outputs.
You call the API against the same documents and receive Markdown as the output, without wiring together a separate converter or building a second processing step. For developers already familiar with Smart Data Extraction, Markdown becomes another direct extraction target rather than a separate workflow.
For a pipeline that currently reads structured output and converts it downstream, this replaces custom conversion logic with a supported SDK call. What lands in your ingestion code is already in the format your models consume.
Why the Conversion Step Was Costing You Structure
It is tempting to treat text extraction as a simple solved problem. The text form the page is captured in data and easy to process. In practice, the structure lost from the extraction shows up as failures on the way out.
Chunking gets arbitrary. Most chunking strategies split on headings, because headings mark where one idea ends and the next begins. Strip them out and you are splitting on character counts instead, cutting through the middle of arguments and stranding the conclusion of one section at the top of a chunk about something else.
Tables lose their relationships. In plain text, a table often becomes a run of headers and values with the visual grid removed. A model may see “Q1,” “Q2,” “Revenue,” and “$4.2M,” but it may not know which value belongs to which quarter or whether the number is revenue, cost, or margin. The answer can sound confident because all the right words are present, even though the relationships between them were lost.
Reading order breaks on real layouts. Multi-column documents, sidebars, and pull quotes will interleave when read naively. The retrieved passage becomes two unrelated half-sentences spliced together.
Provenance gets weaker. When heading hierarchy survives, you know a retrieved passage came from a specific subsection of a specific document. That context is what lets you show a user where an answer came from, and what lets a reviewer check it.
None of this produces an error. It produces a system that passes testing and is quietly wrong in production, which is considerably worse. And each one of these failures traces back to the same cause: Markdown reconstructed from flat text is a guess about structure, made after the evidence for that structure has already been discarded.
Built From the Document Structure, Not the Text
The output is generated from the document structure that Smart Data Extraction derives, not from a text dump that gets patched up afterwards.
That distinction is the entire feature. Apryse's document structure intelligence identifies headings, lists, tables, reading order, and inline formatting as structure during extraction, while the layout evidence is still available. The Markdown is a direct expression of that model. Nothing is inferred from spacing or fonts, and nothing has to be recovered, because nothing was thrown away.
What survives into the output:
- Paragraphs in reading order
- Heading levels 1 through 6
- Nested bulleted and numbered lists, including decimal numbering
- Tables with headers, merged cells, and content
- Nested tables, with inline HTML enabled
- Images, with alternative text and hyperlinks
- External and internal links
- Referenced bookmarks, as HTML anchors
- Text boxes, rendered as block quotes where appropriate
- Bold, italic, strikethrough, superscript, and subscript
Merged cells and nested tables are worth calling out. They are where most conversion tools give up, and they are common in exactly the documents enterprises care about most: financial statements, regulatory filings, clinical protocols, and insurance schedules.
Scanned material goes through the same path. For image-based PDFs, hidden text is reprocessed with OCR before the Markdown is generated, so a scanned archive is treated with the same structural understanding as a digital-native file. That matters, because the corpora most in need of this treatment are rarely the clean ones.
One API Instead of Another Pipeline Step
Markdown conversion is now available as a Smart Data Extraction API, so it becomes part of the extraction step rather than a separate stage you have to design, deploy, and maintain. Instead of extracting structure, handing it to another converter, and then validating whether the Markdown still reflects the source document, the pipeline can request Markdown directly from the SDK.
That simpler architecture has a practical benefit: fewer handoffs where structure can be lost. The same document understanding that identifies headings, reading order, lists, and tables is used to produce the Markdown output, which is harder to preserve if Markdown is reconstructed later from plain text or stitched together from multiple libraries.
It also gives teams a cleaner alternative to cloud conversion services. Those services can be convenient for public or low-sensitivity content, but they add another vendor boundary, another network hop, and another review for documents with privacy, residency, or governance requirements. With Apryse, conversion runs server-side inside your own infrastructure.
It is also easier to operate than a custom stack assembled from open-source parsers, OCR tools, layout analyzers, and Markdown writers. Those components can work, but the maintenance burden shifts to your team: tuning edge cases, tracking dependencies, and deciding what broke when a new document layout fails. A supported API keeps that responsibility in the SDK layer.
For teams building AI ingestion, the result is a more direct path from document to model-ready content: one SDK call, one deployment model, and one place to manage document extraction behavior.
Getting Started
Markdown output is part of the Smart Data Extraction add-on. If you already license SDE, it arrives with the Fall release at no additional cost.
- Download the 2026 Fall release of the Apryse SDK along with the Smart Data Extraction module.
- Run the markdown output on your documents
- Use the markdown in your AI pipeline
If you have been relying on third-party PDF-to-Markdown tools, Markdown conversion is now included directly in Apryse Smart Data Extraction, built on the same document-structure understanding used across the SDK.